

Programmatic Tool Calling Needs Intermediate Ledgers
By wGrow Project Team ·
A CFO rejected a multi-million-dollar reconciliation output from our finance crew. The number was correct. She rejected it because the agent couldn’t show which SQL join produced it, and nobody in the room could either.
That is the failure mode of managed tool loops without an application-owned commit point. Native tool calling lets the model choose the next tool call and consume the returned data. Depending on the runtime, your application may see the call and the result, but it does not see the model’s private reasoning between them. If you only keep the final answer, you have a transcript fragment, not a defensible audit ledger. The convenience is real. So is the cost: once the answer arrives, the intermediate scratchpad is gone.
The black box of native tool calling
The pattern looks like this. The model decides to call a tool and reads the result. It picks the next call, filters or joins what it has, and produces a conclusion. You may see the tool call and the tool result. What you don’t get by default is an application-owned commit point for every intermediate artifact and decision that influenced the next step.
For a chatbot, that’s fine. For a finance close, it’s a defect.
Auditors don’t ask whether the answer is right. They ask how the system got there. “The model did it” is not an evidence trail, and without a trail the output will usually fail review, even when every figure ties out.
Better models make this worse. They keep getting better at chaining tool calls with less supervision, and each gain moves more decisions out of your sight. I won’t guess at specific releases here. The architectural point holds for any loop where the model chooses the next action and consumes the result before your application commits the evidence: the more capable the loop, the easier it is to lose the trail.
The LLM is a query planner
Stop treating the model as a calculator or a monolithic executor. Treat it as a query planner.
A database planner doesn’t fetch your rows. It emits a plan, the engine executes it, and anyone can inspect the plan afterwards. Apply the same split to agents:
- The model outputs instructions: a SQL string, a fetch request, an extraction spec.
- Your environment executes them, using deterministic code, your database and your network egress.
- Every external input, intermediate output and application-visible note routes through your storage layer before it returns to the model’s context.
The model never sees an external tool result you haven’t recorded. That rule is the whole pattern: facts from tools have to pass through your ledger before they can influence the next step.
It isn’t free. Native loops need fewer lines of code and fewer round trips, so you give up some latency and a good deal of orchestration code in exchange for a record you can defend. For any workload where a human signs off on the output, I think that trade is right. For low-stakes work, it may not be.
Reconciling ledgers in the finance close crew
We shipped a finance close crew to automate monthly reconciliations for a corporate client. Our first design let the model query the database and summarise discrepancies in memory. It was fast, and the summaries read well. The client rejected it immediately, because nobody could reproduce a single figure.
So we decoupled intent from execution. The redesigned flow runs like this:
- The agent writes a SQL query as strict text output. It does not run it.
- Our system validates the query and executes it over a read-only connection.
- The system logs the exact SQL string as executed.
- The derived result table goes to an object store configured for append-only retention, addressed by its content hash. In practice that means versioning plus a WORM/Object Lock-style control, or an equivalent store the application role cannot overwrite.
- The model receives the table, then proposes the next step or synthesises.
The final synthesis must carry primary keys mapped to every data point. A reconciled total isn’t a bare number. It’s a number plus the row identifiers that produced it.
Now the auditor can click a final figure and see the exact table state at execution time. The CFO’s question has an answer, and it takes seconds to reach.
One side effect we hadn’t planned for: debugging got easier. When a figure looks wrong, we read the SQL the agent wrote, and the error is often visible in the first few lines.
Tracing hallucinations in the verification pipeline
The second example fails differently. We built an article verification pipeline for a media client, one that checks manuscript claims against source documents.
Early tests showed the model hallucinating source context when it read live URLs directly in memory. That caused two problems. The page could change between runs, so a failure couldn’t be replayed. And when the model misquoted a source, we couldn’t tell whether it had misread the page or never seen that text at all.
We added an intermediate extraction step to ground the model:
- The system scrapes the URL and stores the raw HTML text in an AWS S3 bucket.
- The model must cite exact character offsets from that static artifact.
- The system checks that the cited offsets exist and that the text there matches the quoted passage.
Now when a hallucination occurs, we can trace it to a specific source snapshot. The stored artifact proves what the model saw at execution time, and offsets that point at unrelated text get caught mechanically, before a human reads the output.
There’s a limit, though. A mechanical check confirms the quote is real, not that it supports the claim. Judging support still takes a second model pass or a human. What the snapshot gives us is a fixed input to judge against.
The finance case is about reproducing a computation. The verification case is about freezing an input. Both follow the same discipline: nothing the model reasons over is allowed to exist only in memory.
Building the intermediate ledger schema
- trace_id
- — UUID
- step_sequence
- — INT
- tool_name
- — VARCHAR
- raw_llm_instruction
- — JSONB
- deterministic_output
- — JSONB
- execution_timestamp
- — TIMESTAMPTZ
- sha256_hash
- — VARCHAR
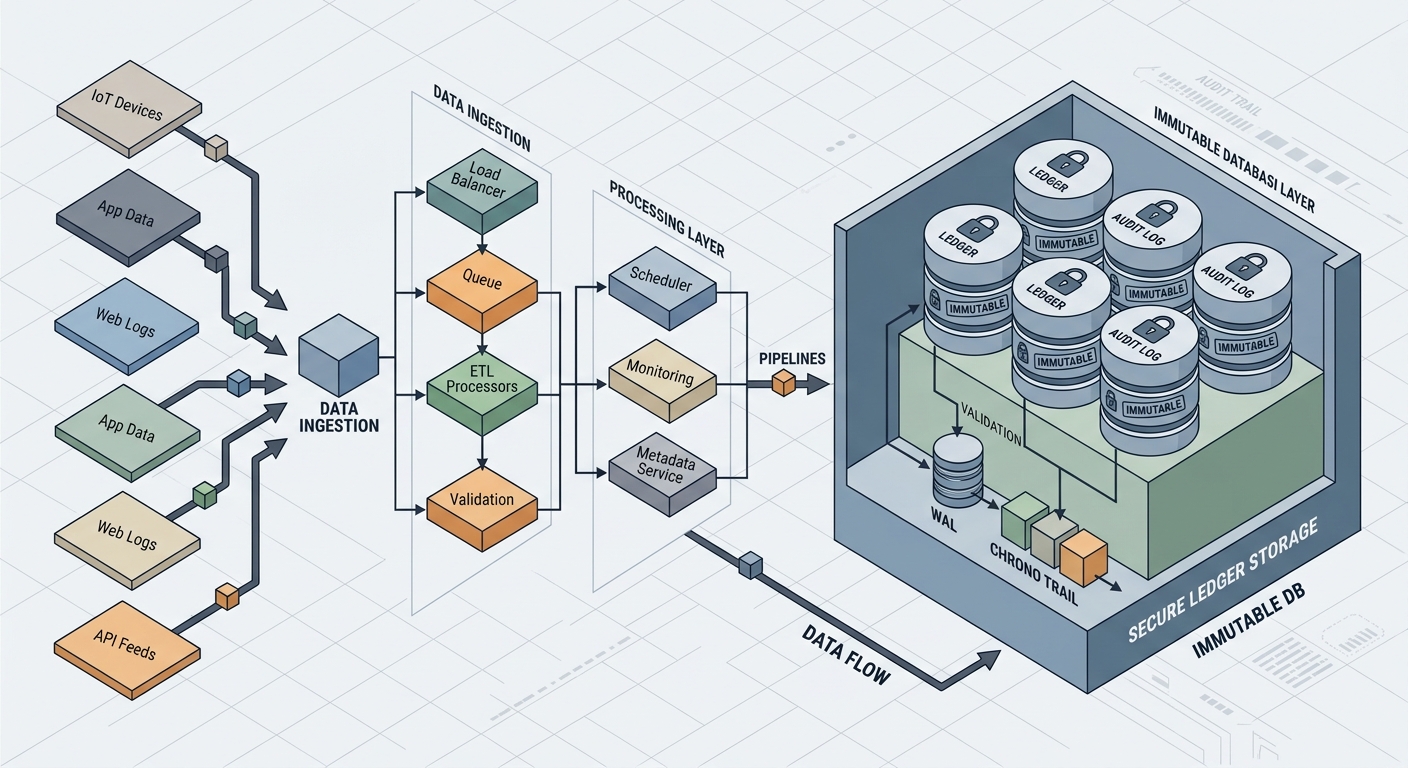
Capturing this record takes a rigid schema, not a log file. Across our agent crews we use a standard PostgreSQL table with one row per tool execution step.
| Field | Type | Purpose |
|---|---|---|
trace_id | UUID | Groups every step of one agent run |
step_sequence | INT | Orders steps within the trace |
tool_name | VARCHAR | Which tool executed |
raw_llm_instruction | JSONB | Exactly what the model asked for |
deterministic_output | JSONB | Exactly what our code returned |
execution_timestamp | TIMESTAMPTZ | When it ran |
sha256_hash | VARCHAR | Hash over inputs and outputs |
The hash is what turns a debug log into an audit record. It’s generated from the inputs and outputs at write time, so if someone edits a row afterwards, the recomputed hash no longer matches the stored one. Pair it with append-only database permissions so the application role can’t update or delete rows. Still, a hash stored beside the data only deters casual edits. For stronger guarantees, fold the previous row’s hash into each new hash, or periodically anchor the latest hash somewhere the application can’t write.
Large payloads, like derived tables and raw HTML, go to the blob store. The row keeps the content hash and a pointer. Don’t stuff a 50 MB table into JSONB.
Retain, redact, discard
Not everything deserves the same treatment. Before a crew ships, we sort its intermediate artifacts into three classes:
- Retain. Anything a figure or a claim depends on: executed SQL, derived tables, source snapshots, offsets. Keep these for the audit retention period.
- Redact. Artifacts carrying personal or commercial data the auditor doesn’t need to see in full. Store the hash and a redacted view, and keep the unredacted original under tighter access.
- Discard. Model scratch work with no bearing on any output, such as abandoned plans and formatting drafts. Drop it on purpose, and write the policy down.
What matters is that discarding becomes a decision someone made. In a native loop, it’s an accident of how the loop was built.
The engineering mandate for production AI
In enterprise settings, trust rests on more than model benchmarks. It depends on how well you can observe the system around the model.
Don’t wait for a compliance team to demand a trail after a bad output lands in a signed report. Retrofitting hurts, because the evidence you need was never captured. You can’t reconstruct a join that only ever existed in a context window.
Build the ledger into the core of the agent architecture now:
- Make the model a planner that emits instructions as text.
- Execute everything in deterministic code you own.
- Write every step to the ledger before the result returns to the model.
- Decide, per artifact class, what is retained, redacted or discarded.
Native tool-calling loops will keep improving, and they’re a good fit for exploration and prototyping. But for anything an auditor may one day question, keep the execution on your side of the line. If you can’t prove the intermediate steps, don’t call the system production-ready.