

Cursor Blame Makes AI Authorship A Permanent Audit Surface
By wGrow Project Team ·
The End of Plausible Deniability
| 1 | { | |
| 2 | "schema_version": "1.0", | |
| 3 | "reject_anonymous": true, | ← ① |
| 4 | "allowed_models": [ | |
| 5 | "claude-3-5-sonnet-20241022" | ← ② |
| 6 | ], | |
| 7 | "ip_indemnity_verified": true | |
| 8 | } | |
| 9 |
- ① Blocks commits lacking author provenance.
- ② Whitelists models covered by enterprise MSA.
For two years, developers copied logic from a browser tab into an editor and committed it under their own name. The repository alone usually could not prove otherwise. Git recorded who committed a change, not who or what wrote it, so the practice went unchallenged.
That gap is narrowing. Where the coding tool records model provenance alongside commits, that metadata can turn AI authorship from a private workflow detail into an auditable repository artifact. “Co-authored by AI” used to be a joke line in a readme. When that provenance is committed and preserved, it becomes evidence for review: a way to separate code a human claims directly from code produced with a vendor model.
An AI-authored diff leaves an audit trail only if the tool records provenance and the repository enforces preservation of that metadata. We use that on our own projects. Our pre-commit hook checks the project’s provenance manifest. Commits that declare AI-generated lines but do not map to an approved model ID in our audit-manifest.json are rejected. The hook is a guardrail, not a lock. Anyone can bypass it with --no-verify, so we back it with a server-side check and code review.
We don’t allow anonymous code.
Auditing a Government Vendor Portal
On a recent public-sector portal delivery, the requirements on data sovereignty and software licensing were not negotiable. The risk we worried about most was an autocomplete agent reproducing a copyleft (GPL) snippet and carrying it into the production branch unnoticed.
Reviewing the whole monolith by hand was the wrong answer. It’s slow, and reviewers skim. So we joined git blame output with the repository’s provenance manifest and filtered the history on that combined view. Blame alone only maps lines to commits and authors; the manifest is what says which of those lines came from a model. We isolated the files and functions with a high concentration of synthetic lines and pointed our senior engineers at those. The licensing audit became targeted rather than exhaustive.
The approach has limits. It only sees code from tools that record metadata, so a snippet pasted by hand from a chat window slips past it. That’s why a standard license scan still ran alongside.
What the metadata gave us was evidence of the review path, not proof that every unauthorized open-source snippet had been excluded. It’s a record of what was reviewed and why. When a client’s legal team asks how we know, we have something better than a verbal assurance.
Re-writing the 2024 Master Services Agreement
A software studio bills clients for intellectual property. If it can’t show clear title to that IP, the contract fails at its foundation.
In early 2024, we updated our standard Master Services Agreement to deal with synthetic code head-on. The clause assigns to the client whatever rights we hold in AI-generated code. Separately, it states that any cover against copyright infringement claims depends on the indemnity terms of the underlying AI platform provider (OpenAI or Anthropic, for example), and that those terms are conditional.
That’s a dependency chain, and the contract says so. The client gets the rights we can assign. We get infringement cover only if our upstream provider gives it, and provider indemnities come with conditions and exclusions set out in the applicable provider terms or enterprise agreement. The project scope records which provider terms the delivery relies on. The client is entitled to know that structure exists.
We don’t leave AI usage unsaid. It’s declared in the project scope as a legal dependency.
Managing the Agent as a Subcontractor
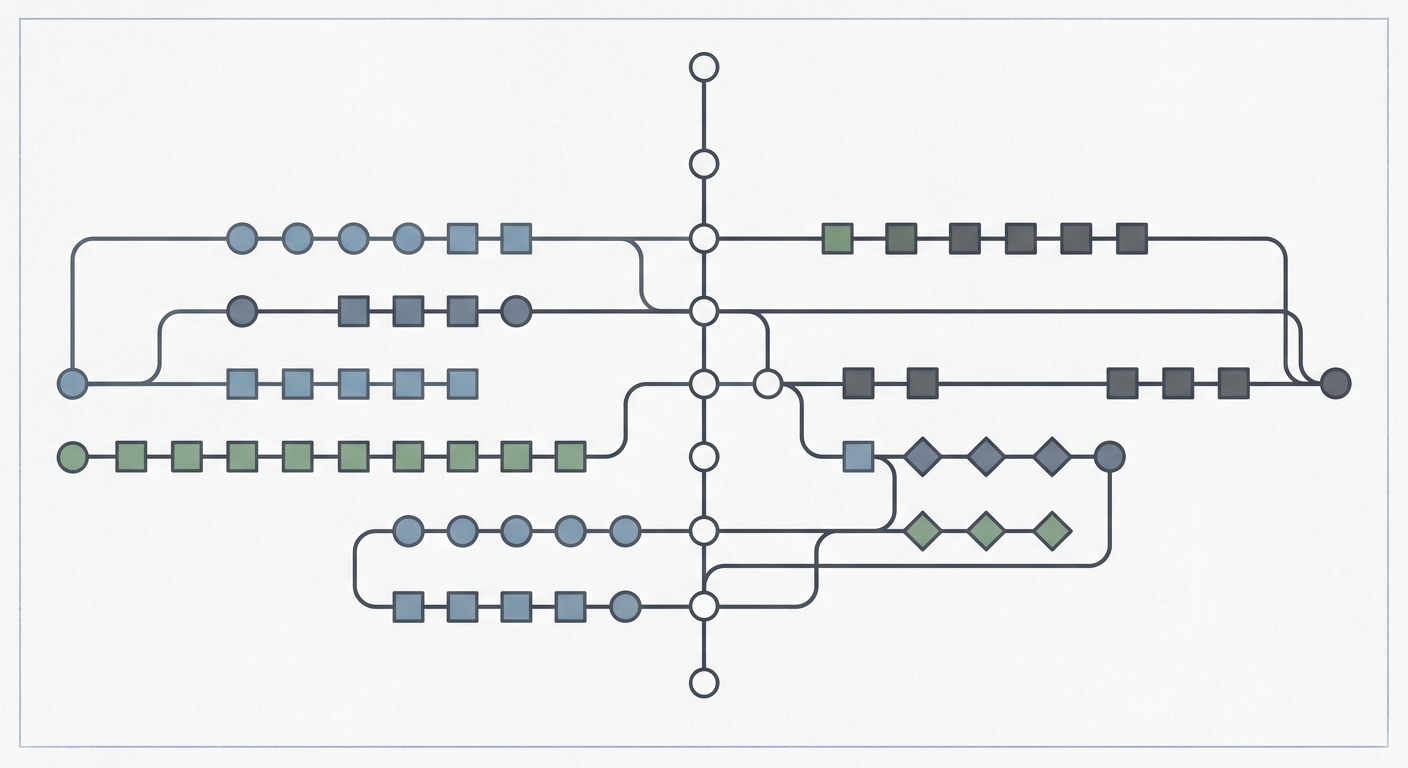
- Human Engineer
- claude-3-5-sonnet
- gpt-4o
Much of the liability in modern software delivery comes from treating the model as an invisible ghostwriter. A ghostwriter has no contract, no warranty, and no name on the delivery note. When something breaks, nobody can say who is accountable.
Enterprise CTOs and procurement teams need a different mental model. Treat the AI as a documented subcontractor.
Take a hypothetical. A human subcontractor writes 40% of a critical billing microservice. Procurement would demand their name, their SLA and their indemnity clause before signing off. A coding agent should meet the same standard: which model, which version, what share of the code, and what the provider’s indemnity covers.
In practice, custom enterprise software should ship with AI authorship percentages attached to the delivery manifest. That isn’t exotic. It’s the same paperwork you already require from any other party that contributed to the work. The percentages will be approximate, because a line a human heavily edited is hard to classify. Even so, an approximate figure beats no figure.
The Immediate Cost of Unquantified Risk
In our workflow, the coding tool emits model IDs into a repository-side manifest (audit-manifest.json), and a server-side check rejects commits where that manifest is missing or inconsistent. This is our own implementation, not a standard feature; it only works with tools that expose that metadata. Where that metadata exists and nobody reads it, the record sits unused.
If nobody is reading it, your organization is carrying unquantified licensing risk. It won’t show up on the balance sheet as a line item, but it’s there. A repository full of untracked synthetic code is an asset whose title you can’t fully verify.
So the procurement rule is simple. When an external vendor delivers a custom enterprise application, accepting the repository without a provenance manifest or equivalent audit artifact that states the split between human and agent lines is a gap in procurement diligence. Ask for the manifest. Ask which models were used, and which provider indemnities the vendor relies on.
Don’t wait for case law to settle. Courts will take their time, and your contracts can’t wait for them. Treat the synthetic lines in your git history as a legal boundary now, and manage the liability accordingly.